Skip to content
Please update to the latest release 0.77.2 to address Multiple CVEs.
Deployment

Deployment Overview

Velociraptor offers many deployment options that allow us to operate in all kinds of environments.

There really is no single “right” way to use Velociraptor, so in this section we’ll describe the commonly used (and therefore recommended) deployment modes. We’ll guide you through the main decisions that you’ll need to make, and point you to additional resources for less commonly used features and options.

If you just want to get a simple deployment up and running then please see our Quickstart Guide.

If you’re really in a hurry you can start a self-contained Instant Velociraptor on your local machine which will allow you to experiment and get a feel for how Velociraptor works.

Using Velociraptor integrated with Rapid7 InsightIDR?

These deployment steps apply to open source Velociraptor only. Read the InsightIDR documentation to learn more about how Velociraptor is deployed with the Rapid7 Insight Platform.

Typical Deployment
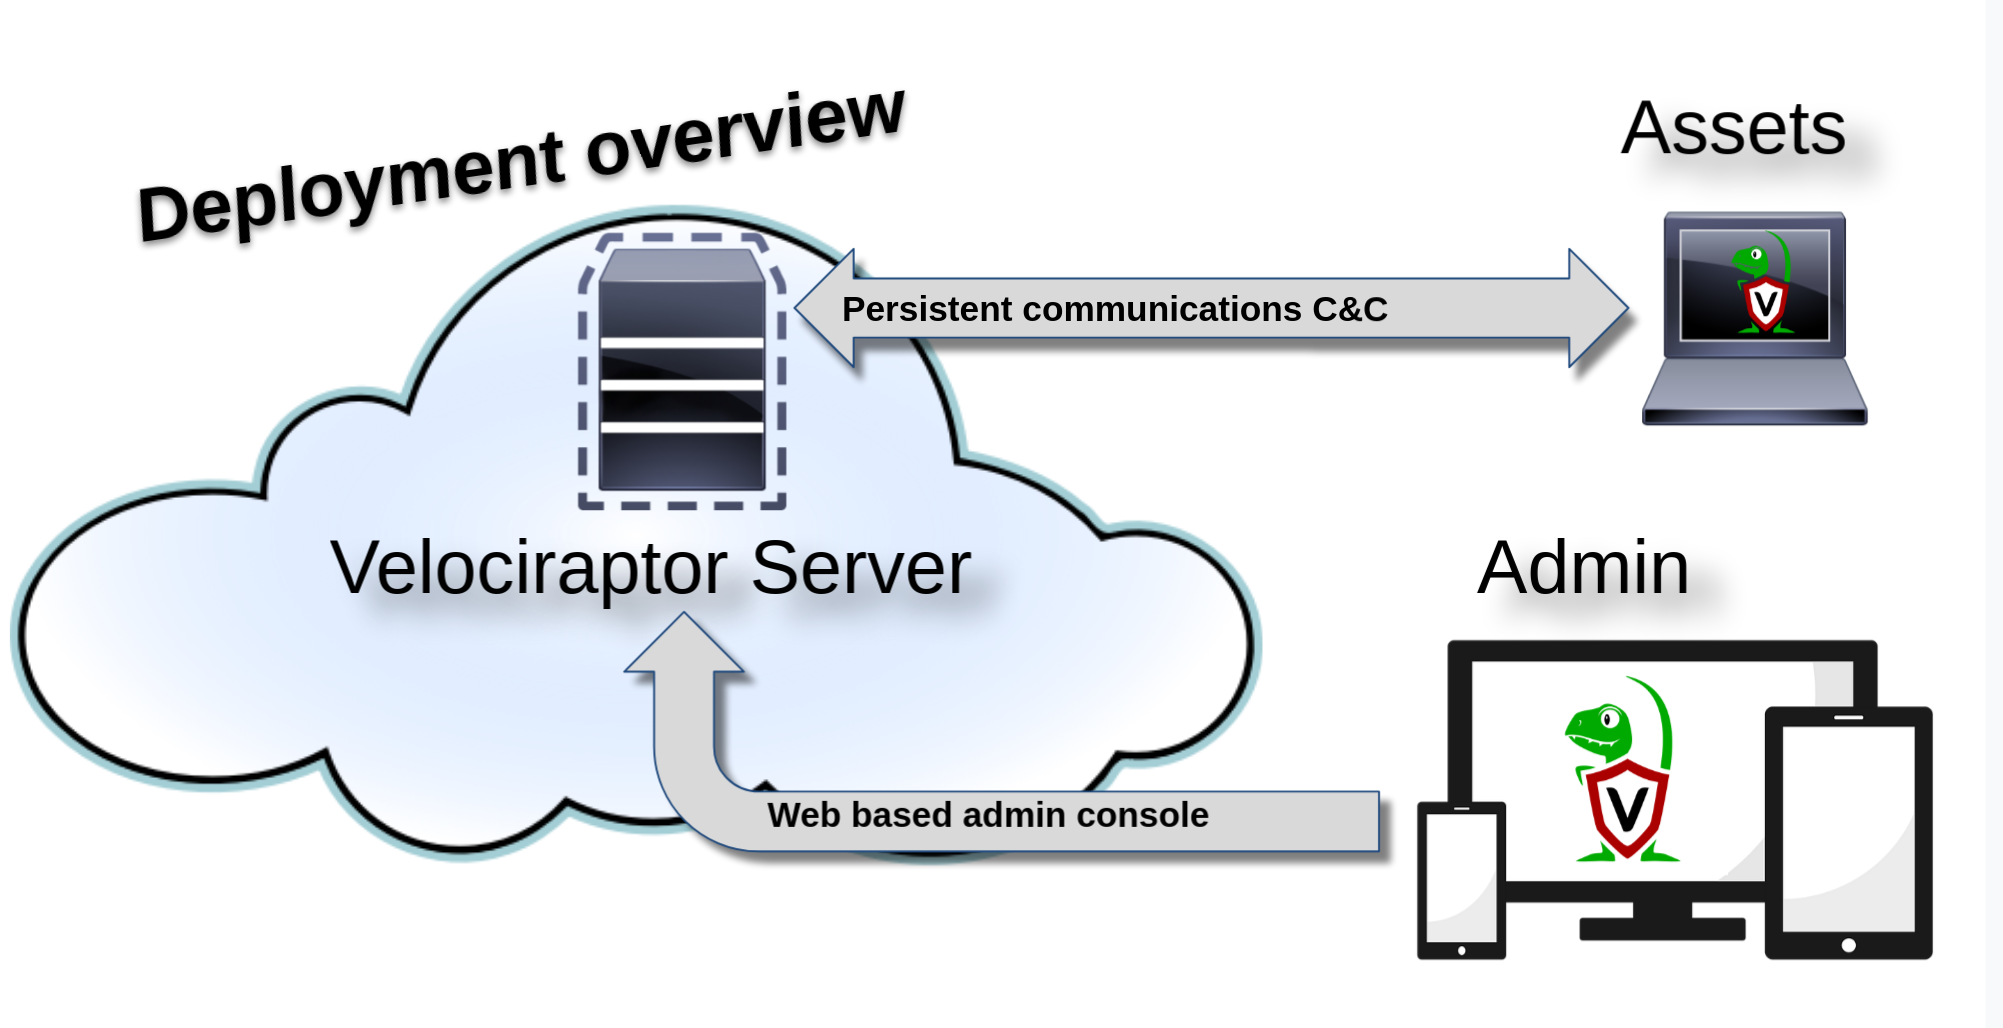
A typical Velociraptor deployment

We use the following terminology for Velociraptor’s main components:

  1. A Client is an instance of Velociraptor running on the endpoint, that is it’s our endpoint “agent”.
  2. The Frontend is the server component that communicates with the client.
  3. The GUI is the web application server that provides the administrative interface.
  4. The API is our gRPC-based API server.

Each deployment relies on a unique configuration file, which include information such as connection URLs, DNS names, and unique cryptographic keys. Since key material is unique to each deployment, one Velociraptor deployment cannot connect with another deployment.

The Velociraptor Server is typically deployed on a cloud VM and runs a number of components as separate threads. The server provides an Admin UI - a Web application that can be used to control Velociraptor and orchestrate hunts and collections from the endpoints.

The endpoints themselves run the Velociraptor Client, typically installed as a service. Velociraptor Clients maintain a persistent connection with the server. This allows the client to execute tasks issued by the server in near-realtime. Many other solutions rely on periodic polling between endpoint and the server leading to latency between issuing a new task and receiving the results - not so with Velociraptor!

Velociraptor does not use any external database - all data is stored within the server’s filesystem in regular files and directories. This makes backups and data lifecycle management a breeze. You do not need any additional infrastructure such as databases or cloud storage services. Due to it’s file-oriented design, Velociraptor is compatible with distributed file systems such as Amazon EFS, Google Filestore or generic NFS.

A typical deployment includes the following steps:

  1. Plan your deployment and generate a configuration file for the server which includes the main configuration options.
  2. Create a server installation package that includes the generated configuration file.
  3. Set up a VM or a physical server to host the server component.
  4. Install the server package. Once installed you will be able to access the Admin GUI and front end.
  5. Create client installation packages for your target operating systems (for example, MSI for windows).
  6. Deploy the client installation packages using your preferred deployment solution.

Deployment Platforms

Velociraptor only has one binary per operating system + architecture combination. We do not have separate client binaries and server binaries. The binary can act as a server, a client or a number of utility programs depending on the command line parameters passed to it.

While this technically allows you to run the server or the client on any platform that we have a binary for, please note that the server is only fully supported on Linux. This is mainly due to performance considerations inherent in other platforms such as Windows. However for non-production deployments - for example evaluation, development or testing - it might be convenient for you to run the server on a different platform, and you may decide to do so, but please keep in mind that for production deployments the server should run on Linux. Issues with other platforms will receive limited support.

Binaries for the most common platforms and architectures are available on our Downloads page.

Deployment Milestones

At a high level, deploying Velociraptor consists of 3 tasks: setting up a server, deploying clients, and granting user access to the server’s web UI.

Task 1: Deploy a Server

Task 2: Authorize Users

  • Grant users access to the Velociraptor server’s web UI

Task 3: Deploy Clients

  • Deploy clients on your endpoints using one or possibly a combination of the following methods:
    • Run clients interactively
    • Install the client as a service using a custom installer package
    • Agentless Deployment
    • Create and run “offline collectors” (which are essentially out-of-band clients)

Other ways to use Velociraptor

While deploying Velociraptor in client-server mode, as described above, is the recommended deployment model and typical of most deployments, Velociraptor’s extensive capabilities can also be used in innovative and unconventional ways - even ones we haven’t thought of yet!

There isn’t a single prescribed way to use Velociraptor. We would love to hear about your creative ideas and unusual use cases so we can continue to make Velociraptor better for everyone.

The following are some other (less conventional) ways that you can use Velociraptor.

“Instant Velociraptor”

If you want to instantly start a Velociraptor instance for evaluation, learning, experimentation, testing, or any another reason, you can run “Instant Velociraptor”. This is a fully functional, self-contained Velociraptor system on to your local machine. In this mode of operation you’ll get the server plus a single client running within the same process on your machine. All the necessary configuration is taken care of automatically. With a single command you can be ready to dive right into the fun stuff!

To do this, download the Velociraptor executable for your platform from the Downloads page and run the gui CLI command.

./velociraptor gui

Since this mode is not intended to be a production server, it is fine to run this on any platform. The client capabilities do vary per platform, but the server component is identical across platforms. This mode is especially useful for testing and artifact development because it allows you to run VQL directly on the target operating system via Velociraptor notebooks.

In this mode:

  • The server only listens on the local loopback interface.
  • The client connects to the server over the loopback.
  • A data store directory is set to the user’s temp folder, unless specified otherwise (see note below).
  • A single administrator user is created with the username admin and password password.
  • The default web browser is launched with those credentials to connect to the GUI.
Instant mode automatically enrolls a single client

Instant Velociraptor: Persisting your data

By default the gui command uses the temp folder as it’s data store (by default a subfolder named gui_datastore). The gui command also automatically creates new server and client configuration files in this datastore folder. This allows you to re-run the gui command and get the same working environment with persistent data.

However some operating systems clean out the temp folder periodically or during a system reboot, in which case your environment and data will NOT persist (i.e. it will be lost). To avoid this you can specify a different data store directory using the --datastore flag and point it to a location where your data will be persisted. If at any time you want to start with a fresh instance you can either delete the old datastore folder or point it to a new folder using the --datastore flag.

Command line investigation tool

We can run any VQL query or any Velociraptor artifacts from the CLI and optionally write the results to local files. Using this capability it’s possible to use Velociraptor as a command line DFIR “Swiss Army Knife” or build it into forensic data processing pipelines.

Most CLI-based forensics tools perform a specific, limited set of functions. However with Velociraptor’s CLI you have full access to VQL and all the functions and plugins that Velociraptor provides. So this capability can be used to inspect a live system or analyze acquired file-based forensic artifacts, for example Sqlite databases or event logs.

The CLI provides the following commands which support this mode of operation:

The query command

The query command accepts any VQL query and runs it against the local system. The results can optionally be written to file in a variety of formats.

Example
velociraptor.exe query "SELECT * FROM pslist()" --format jsonl --output pslist.json

The artifacts command

The artifacts collect command runs any Velociraptor artifact which can contain one or more packaged VQL queries.

You can use artifacts list to list the available artifacts, and artifacts show to view the contents of a specific artifact.

  artifacts
    list [<flags>] [<regex>]
    show <name>
    collect [<flags>] <artifact_name>...

All the built-in Velociraptor artifacts are available within the binary.

Custom artifacts can be used too by pointing the binary to a folder containing these artifacts using the --definitions flag.

As with the query command, the results can optionally be written to file in a variety of formats.

Examples
velociraptor.exe artifacts list ".*Audit.*"
Server.Audit.Logs
Windows.System.AuditPolicy
velociraptor.exe artifacts show "Windows.System.AuditPolicy"
name: Windows.System.AuditPolicy

description: |
   Artifact using auditpol to retrieve the logging settings
   defined in the Windows Audit Policy.

   Use this artifact to determine what Windows event logs are audited
   and if there are any discrepancies across the environment.

type: CLIENT
...
velociraptor.exe artifacts collect "Windows.System.AuditPolicy" --format json --output auditpol.json

“Instant Velociraptor” as a local investigation tool

While Instant Velociraptor is normally used for testing or demonstrations, it can actually be used as a standalone GUI-based forensic tool.

The gui command starts the server and a single client within a single process. This client is no different from one that’s separately deployed, and can be used to interrogate the local system as you would do for any remote client.

Minimizing data pollution

Obviously this idea is not suitable for all investigation scenarios as the server component will need to write data to it’s datastore. Also, using a web browser on the target machine and any other activity risks polluting the forensic data. If these risks are acceptable to you, you may still want to minimize them by:

  • locating the datastore on an external drive using the --datastore flag.
  • changing the writeback and tempdir locations in the client config to also be on an external drive.

“Instant Velociraptor” as an desktop environment for analysts

Instant Velociraptor can also be used as a standalone graphical forensic desktop environment, for acquired forensic artifacts.

Velociraptor notebooks have access to the local filesystem, and can therefore read any files within it and work with the extracted data.

In addition to forensic artifacts you can also read the most common text-based file formats, for example json or csv, and then work with that data in the notebook interface. In this way Velociraptor notebooks can function very similarly to Jupyter notebooks with the Python Pandas library, which were indeed a significant inspiration for Velociraptor notebooks. In this mode of operation, the client component may not be needed and you can disable it by adding the --no-client flag to the gui command.

However the client component may be useful if you want to use remapping which will allow you to inspect and analyze disk image files using Velociraptor’s dead disk feature. The gui command creates the client config file in the datastore folder, to which you can add the remapping config, if needed.

Standalone offline collectors

Offline collectors are usually created with the expectation that the data will be imported into a Velociraptor server, but this doesn’t have to be the case. You may just be interested in extracting the data and working with it elsewhere using other tools. In that case the only reason for having a Velociraptor server is to create the offline collector, and you can use an Instant Velociraptor for that purpose.

It’s important to note that Velociraptor offline collectors have all the capabilities of a normal Velociraptor client. They are not limited to doing file acquisition! You can run any Velociraptor artifact, including custom ones, and the results are written to jsonl formatted files (and/or CSV format, if you prefer) which can be read by most data processing tools.

As a variation on this idea, you can import the offline collection containers back into the standalone (i.e. non-networked) Instant Velociraptor, and work with them the same as you would with data collected from network-connected clients. That is, an Instant Velociraptor deployment using only offline collectors amounts to a sneakernet Velociraptor deployment!

Collections Over SSH

Collections Over SSH

What’s next?

Quickstart Guide
The goal of this guide is to help you get a Velociraptor server deployed with one or more clients, as quickly and simply as possible. The Velociraptor server will be configured to use self-signed SSL certificates and Basic authentication, which is a relatively simple configuration scheme suitable for short-term (e.g. testing/evaluation) non-production use, ideally on a private network. For production deployments, Single Sign-on (SSO) authentication is strongly recommended. However it requires a slightly more complicated certificate scheme and public DNS configuration. To explore these other options please see the Deployment section.
Server Deployment
How to plan and implement your server deployment
Organizations and Multi-tenancy
Velociraptor supports multiple orgs in a full multi-tenancy configuration.
Deploying Clients
How to run, and optionally install, clients on the most common platforms.
Offline Collections
In this section we look at a less conventional method of collecting data from endpoints. One of Velociraptor’s many strengths is its ability to deal with the variety of challenging environments that realworld DFIR throws our way. How do offline collections work? At it’s core, the Velociraptor is just a VQL engine! We give it VQL to run, in the form of artifacts, and it gives us back data (which may or may not include files). Normally the Velociraptor server gives the client the VQL to run, the client runs (“collects”) it, and the server receives the results from the client. Note that the collection step occurs independently of the server, with the server only being involved before and after the collection.
Velociraptor Security Configuration
Velociraptor is a highly privileged service with elevated access to thousands of endpoints across the enterprise. It is therefore crucial to secure the deployment as much as possible.
Backups and Disaster Recovery
Strategies for backing up and restoring a Velociraptor deployment.
Server Performance and Monitoring
In this page we discuss some of the performance limitations of the platform. It is important to understand how performance affects the framework and how Velociraptor manages finite resources to scale up efficiently.
Server Logging
Configure Velociraptor server logging to capture operational events to local files, forward them to a remote syslog server, or both.
Configuration File Reference
This is an annotated server.config.yaml with complete explanations for all options currently available. The values you see are the default values that will be used when the option is omitted. If an item is a list, the default list applies only when the item is empty. If you want to preserve some of the default items in the list, you should copy the entire default list and set it. version This is the version of the Velociraptor binary used to generate this configuration file. It simply annotates the produced file and can not be changed. When Velociraptor loads the configuration file, this field will be updated so for example velociraptor config show will update this to the present version. version name version > name velociraptor Name of the agent - always “velociraptor” version version > version 0.74 The release version on GitHub. commit version > commit f3264824 The commit at which this binary was built. This is more accurate than the version for reporting issues etc. build_time version > build_time 2022-04-13T02:24:43+10:00 The time the binary was built. ci_build_url version > ci_build_url https://github.com/Velocidex/velociraptor/actions/runs/3391188003 The URL to the Github Action CI job that built this binary. Not all release binaries are built on the Github CI due to signing requirements. compiler version > compiler go1.19.2 The version of the Go compiler that built this binary install_time version > install_time 1680267359 The time the client was installed (as written in the writeback file). system version > system linux The operating system this binary is running under. architecture version > architecture amd64 Client The Client block will be copied into the client.config.yaml and it is expected to be used by clients. It contains no secrets and can be embedded into clients. The server must also have this block as it needs to refer to client specific information sometimes. Client Crypto The Crypto options specifies cryptographic options. Client > Crypto root_certs Client > Crypto > root_certs -----BEGIN CERTIFICATE----- <certificate 1> -----END CERTIFICATE----- -----BEGIN CERTIFICATE----- <certificate 2> -----END CERTIFICATE----- These are the root CA certs the client will trust. This is needed when going through a MITM proxy. Certificates are in PEM format one after the next. Certificates do not have to have the CA basic constraint! certificate_thumbprints Clients may connect to servers which use a self-signed certificate. This list allows to specify a set of certificate thumbprints (SHA256) which are used to validate TLS server certificates. Fingerprints can be generated with the OpenSSL command line utility: openssl s_client -connect www.google.com :443 < /dev/null | openssl x509 -fingerprint -sha256 -noout Certificate thumbprints may or may not include colon characters. Capitalization of the hex digits is ignored by Velociraptor. A thumbprint of any of the forms used below (or combinations thereof) is fine. Client > Crypto > certificate_thumbprints E6:E2:8B:35:CE:C5:BA:C4:53:C5:AF:BF:2B:76:34:62:40:5C:D0:60:80:E1:30:1A:A7:A5:A9:DA:0C:8B:11:E1 Client > Crypto > certificate_thumbprints E6E28B35CEC5BAC453C5AFBF2B763462405CD06080E1301AA7A5A9DA0C8B11E1 Client > Crypto > certificate_thumbprints e6e28b35cec5bac453c5afbf2b763462405cd06080e1301aa7a5a9da0c8b11e1 Client > Crypto > certificate_thumbprints certificate_verification_mode Client > Crypto > certificate_verification_mode PKI Velociraptor supports several ways of verifying TLS certificates. The certificate_verification_mode specifies which of the three modes is applied. Currently, three modes are available: PKI (the default): verify TLS certs against public CA lists, the list of additional root_certs (see above), and the built-in CA cert PKI_OR_THUMBPRINT: the same as PKI with the addition that certificates which have a thumbprint that is present in certificate_thumbprints will be accepted as well THUMBPRINT_ONLY: Velociraptor only accepts certificates which have a matching thumbprint in certificate_thumbprints. All other certificates will be rejected. This mode is also known as certificate pinning. allow_weak_tls_server Client > Crypto > allow_weak_tls_server false By default velociraptor uses TLS 1.3 to secure it’s communications. Some networks use a MITM TLS proxy which does not support more secure protocols so this setting can be applied to make the server allow lower TLS versions. client_certificate Client > Crypto > client_certificate -----BEGIN CERTIFICATE----- ... If you want to use mTLS to mutually authenticate clients to the server, place a pem encoded client certificate here. This certificate will be presented to the server before a TLS connection can be made. This is an additional level of security that controls connections between clients and server. It is normally not needed as client connections are controlled via the embedded nonce. However mTLS authentication allows termination of the TLS before the server (e.g. using a reverse proxy). To configure this feature you can create a certificate signed by the Velociraptor CA: velociraptor –config server.config.yaml config api_client –name “Client” api.config.yaml This will create an api config file with the key pair encoded as PEM strings. You can then copy and paste those into the settings below. Only clients configured with these keys can talk with the server To require the frontend to only talk with mTLS authenticated clients, set the Frontend.require_client_certificates to true. client_certificate_private_key Client > Crypto > client_certificate_private_key -----BEGIN RSA PRIVATE KEY----- ... server_urls A list of one or more URLs the clients will try to connect to. When all connections fail the client will back off for a while. Clients will choose one of these at random so it is a good way of achieving fault tolerance and load balancing. As of version 0.72, You can choose to use websockets here for a better experience by setting the URL to start with wss:// Client > server_urls wss://192.168.1.1:8000/ Client > server_urls https://192.168.1.1:8000/ Client > server_urls https://192.168.1.2:8000/ Client > server_urls ws_ping_wait_sec Client > ws_ping_wait_sec 60 When using websockets the server will ping the client every this many seconds. proxy Client > proxy https://proxy:3128/ A URL to a proxy that will be used to connect to the server. Some environments have egress filtering requiring Velociraptor to use a proxy to be able to reach the server. NOTE: We do not support PAC based proxy configurations or Windows domain authentication - you might need to add an allow rule to the proxy config to allow the Velociraptor server URL without authentication. proxy_config Some proxy configurations are more complex. You can specify a more detailed configuration here instead of the proxy parameter above. Client > proxy_config http Client > proxy_config > http <not set> The proxy configuration for http and https urs. https Client > proxy_config > https <not set> proxy_url_regexp A list of url regexp to match the url and connect to the target. Use an empty string to denote direct connection. Client > proxy_config > proxy_url_regexp ^https://localhost/ Client > proxy_config > proxy_url_regexp > ^https://localhost/ pac Client > proxy_config > pac <not set> Location of a PAC file (overrides the above settings). This can be a file:// URL or even a data: url. ignore_environment Client > proxy_config > ignore_environment false If this is set we ignore the HTTP_PROXY and HTTPS_PROXY environment variables. By default we allow these environment variables to override the settings in this file. ca_certificate Client > ca_certificate -----BEGIN CERTIFICATE----- Generated by the config wizard!!! -----END CERTIFICATE----- The Internal Velociraptor CA certificate used to verify the server certificates. Do not change this! This will be generated by the config wizard and can not be replaced. It is only used internally. nonce Client > nonce rKNKAYam310= This is a shared secret between servers and clients. The server will refuse to communicate with clients having the wrong nonce. The nonce is used to group clients into Org Groups - so clients from different orgs have different nonce. writeback_darwin Client > writeback_darwin /etc/velociraptor.writeback.yaml The following are the locations to write the writeback file - this file is used to keep client state. In the default configuration, writeback files persist across uninstall/reinstall cycles to keep the client id consistent. If you don’t want this you can change the location of the writeback to be inside the tempdir_windows directory (it will be removed on uninstall). writeback_linux Client > writeback_linux /tmp/velociraptor.writeback.yaml writeback_windows Client > writeback_windows $ProgramFiles\Velociraptor\velociraptor.writeback.yaml On Windows, if the writeback path starts with HKLM\ the path will be interpreted as a registry key that will be used to store the writeback instead of files on disk. level2_writeback_suffix Client > level2_writeback_suffix l2 If this value is specified, Velociraptor will create a level 2 writeback file. This second file is used as a backup and to write more frequently updated content. This scheme should reduce the likelihood that the file is corrupted to the point that the client id is lost. tempdir_windows Client > tempdir_windows $ProgramFiles\Velociraptor\Tools This is the directory Velociraptor will use for temporary files. If not specified or not writable, Velociraptor will use the $TMP or $TEMP env variable. tempdir_linux Client > tempdir_linux /tmp/ tempdir_darwin Client > tempdir_darwin /tmp/ max_poll Client > max_poll 60 Number of seconds to wait before polling. Typically Velociraptor connections are persistent but will force a re-connection every max_poll seconds to refresh the connection. NOTE that typically Velociraptor reuses TCP connections so this only applies to the HTTP transactions, i.e. The TCP connections are always up. max_poll_std Client > max_poll_std 30 Standard deviation between polls adds randomness to the poll period. This ensures that clients are not synchronized to even up the load on the server. nanny_max_connection_delay Client > nanny_max_connection_delay 0 If this is set, the nanny will exit if we are not able to send messages to the server within this many seconds. NOTE - even a failed connection will reset the counter, the nanny will only fire if the client has failed in some way - e.g. the communicator is stopped for some reason prevent_execve Client > prevent_execve false If this is set, prevent arbitrary code execution on clients. NOTE: This will vastly reduce the capabilities of the client. default_max_wait Client > default_max_wait 60 The default max time to wait before we send partial VQL results. This setting is used to ensure we don’t send too many small requests by batching the rows into time batches. concurrency Client > concurrency 2 Maximum number of concurrent queries the client will allow (default 2). This ensures we do not overwhelm the client by scheduling too many concurrent queries. NOTE: Queries marked as URGENT will skip this control and run anyway. max_memory_hard_limit Client > max_memory_hard_limit 0 If set the client will hard exit when it uses this much memory (in bytes). This is a safety feature to prevent runaway process - ensure this is not set too low. client_info_update_time Client > client_info_update_time 86400 Clients will send a Server.Internal.ClientInfo message to the server every this many seconds. This helps to keep the server info up to date about each client. This should not be sent too frequently. The default is 1 day (86400 seconds). disable_checkpoints Client > disable_checkpoints false When a collection starts on the client, the client writes a checkpoint file so it can detect when it crashed previously and restarted. If this option is set we disable client checkpoints and so we can not report to the server when the client crashes while collecting an artifact. windows_installer These settings are used by the velociraptor service install command. We typically do not use this as we prefer to distribute MSI packages via package management systems. Client > windows_installer service_name Client > windows_installer > service_name Velociraptor install_path Client > windows_installer > install_path $ProgramFiles\Velociraptor\Velociraptor.exe service_description Client > windows_installer > service_description Velociraptor service darwin_installer Settings used by the darwin velociraptor service install command. Client > darwin_installer service_name Client > darwin_installer > service_name com.velocidex.velociraptor install_path Client > darwin_installer > install_path /usr/local/sbin/velociraptor use_self_signed_ssl Client > use_self_signed_ssl true If this setting is true, Velociraptor will expect the server to use self signed TLS certificates. The client will verify the TLS connection by checking that the server certificate is signed by the Velociraptor internal CA. With this setting it is possible to use an IP address for the server URL (not recommended though) pinned_server_name Client > pinned_server_name VelociraptorServer Do not change this! max_upload_size Client > max_upload_size 5242880 The maximum size of the POST request the client will send to the server. Some proxy servers limit the size of POST messages. connection_timeout Client > connection_timeout 300 Maximum timeout for connection retry - the length of time we try a connection before restarting it (default 5 min). disable_compression Client > disable_compression false Disable client/server compression. Typically no need to change this. labels It is possible to pre-label clients using the configuration file. The server will add these labels to the clients automatically upon enrollment. This allows different client packages to be distributed in the real world and have them automatically identified. Client > labels Label1 Client > labels Label1 Client > labels logfile_name Client > logfile_name logfile.log The client normally does not write any logs on the endpoint. However this makes it hard to debug any issues so you can choose to have the client write its logs in a file on the endpoint. The file will be written in an encrypted form which can only be decrypted by the Generic.Client.LocalLogsRetrieve artifact. Path relative to the relevant tmpdir above where client side logs are kept. These logs are encrypted client side and need to be decrypted on the server to read. logfile_size Client > logfile_size 10000000 panic_file Client > panic_file $TEMP/panic.log On Windows, the client usually runs as a service. If a crash occurs while Velociraptor is running as a Windows service the traceback of the error is printed to Stderr, however a Windows service discards these messages. This means that if Velociraptor crashes we lose the panic backtrace which is useful for debugging why it crashed. This setting allows us to specify a path to a log file on the client where Velociraptor will write stdout and stderr in the event of a crash. This feature is currently not implemented for non-Windows platforms where this setting will have no effect. local_buffer Velociraptor keeps a local buffer file to store query results while they are being shipped across the network. There are two types of buffers - an in memory buffer and a local file based buffer file. When the buffer is exceeded the query is paused so it is important to have reasonable size available for the buffer file to prevent queries taking too long (and possibly timing out). Client > local_buffer memory_size Client > local_buffer > memory_size 52428800 Maximum size of the in-memory buffer. When this size is exhausted the query is paused until the data is sent over the network. disk_size Client > local_buffer > disk_size 1073741824 If the disk size of the local buffer is set to 0, no disk file will be used, only a memory buffer will be used. filename_linux Client > local_buffer > filename_linux /var/tmp/Velociraptor_Buffer.bin Where to store the files on the local disk for the various operating systems. filename_windows Client > local_buffer > filename_windows $TEMP/Velociraptor_Buffer.bin filename_darwin Client > local_buffer > filename_darwin /var/tmp/Velociraptor_Buffer.bin insecure_network_trace_file Client > insecure_network_trace_file /tmp/trace.txt Setting this will write clear text network traces to this file. This is used for debugging network communications in complex scenarios (e.g. in the presence of proxies etc). Do not leave this configured in production! This setting will also disable TLS verification for the server name so it will be possible to MITM the client->server connection. NOTE: Velociraptor has 2 layers of encryption - this setting bypasses the outer TLS layer to expose the underlying HTTP communications. Client->server communication still remain encrypted however. server_version The server that created this config file - this is only a hint. Client > server_version system Client > server_version > system linux low_resource_max_cpu Client > low_resource_max_cpu 50 By default when running on a low resource machine we cap the CPU use to 50%. This allows to change that - needs to be between 0 and 100 (100 disables throttling). low_resource_cpu_count Client > low_resource_cpu_count 1 We determine we are running on a low resource machine if the system has less than 2 cores. This allows you to increase the threshold. Set to a large number to disable. dns_cache_refresh_min Client > dns_cache_refresh_min 0 If greater than 0 we install a local DNS cache. This is usually not needed as most operating systems already have local DNS caching resolvers. This DNS cache will be refreshed periodically from upstream. Note that the ttl of the record is currently ignored and we refresh according to this setting. This setting takes effect both on the client and on the server. API This section configures the API service. The API server accepts connections from the GUI gRPC gateway, as well as connections from the gRPC API clients (e.g. with pyvelociraptor). API hostname API > hostname 192.168.1.11 This is the hostname used to connect to - it is used here to copy into new api client configuration files to assist gRPC API connections (e.g. pyvelociraptor). bind_address API > bind_address 127.0.0.1 Interface to bind to - by default only bind to 127.0.0.1 but will need to be exposed on 0.0.0.0 for external pyvelociraptor clients to connect. bind_port API > bind_port 8001 The port to listen on. bind_scheme API > bind_scheme tcp Usually these do not need to be changed. pinned_gw_name API > pinned_gw_name GRPC_GW Do not change this. It is the common name of the certificate that will be trusted to be from the GUI. ACL checks will be disabled for all connections from this name. GUI Configure the GUI admin web application. GUI use_plain_http GUI > use_plain_http false Allows the GUI to start with no encryption - WARNING This only makes sense if you have TLS proxy in front. In fact the GUI will not work without a TLS proxy because the CSRF cookie is still set to secure only. base_path GUI > base_path / You can serve Velociraptor at a sub path of the server. All URLs will then be formed below the base path. public_url GUI > public_url http://velo.example.com/app/index.html The public URL of this server. Change this if you are proxying the GUI using a different URL. allowed_cidr A list of CIDR addresses from permitted networks. If this is not set, permit all connections to the GUI from anywhere. This is useful when you want to limit access to the GUI by IP address but still allow access to clients from any IP, while running both the frontend and GUI on the same port (normally port 443) GUI > allowed_cidr 192.168.0.0/16 GUI > allowed_cidr forwarded_proxy_header GUI > forwarded_proxy_header X-Forwarded-For Header defined by the proxy containing the remote address. This header will be used in the allowed_cidr matching if specified. NOTE: Only use this if you do have a reverse proxy in front of the server. Otherwise an attacker can simply send this header to pretend to come from any IP address. If this setting is specified we take the src address from the header, otherwise from the remote IP address. Default is not set. links Allows additional links to be defined for site customization. GUI > links [0] GUI > links > [0] text GUI > links > [0] > text Google Search The text of the link (visible in the GUI) url GUI > links > [0] > url https://www.google.com Where the link points to. new_tab GUI > links > [0] > new_tab true should the link be opened in a new tab? type GUI > links > [0] > type sidebar The type of links. Currently: sidebar: This link will appear in the sidebar navigation menu context: Will appear as part of the context (right click) menu icon_url GUI > links > [0] > icon_url data:image/svg+xml;base64,.... The icon before the link. This can be a data URL or a link to a png encode GUI > links > [0] > encode plain For context menu the value in the cell can be relayed to the target URL. This setting controls the encoding of the value and the parameter to attach it to. parameter GUI > links > [0] > parameter q method GUI > links > [0] > method GET Can be GET (default) or POST disabled GUI > links > [0] > disabled false If set we ignore this entry completely bind_address GUI > bind_address 127.0.0.1 Bind the GUI to this port. By default: For self signed SSL the GUI will be bound to the localhost only! For Let’s Encrypt deployments the GUI will be bound on 0.0.0.0 making it accessible from anywhere. NOTE: The only valid settings here are 0.0.0.0 for external access and 127.0.0.1 for localhost - Do not specify any other address unless you know what you are doing! bind_port GUI > bind_port 8889 Bind port for the GUI. When using Let’s Encrypt the GUI is bound to port 443 and this setting is ignored because Let’s Encrypt only supports port 443. gw_certificate GUI > gw_certificate -----BEGIN CERTIFICATE----- Generated by the config wizard!!! -----END CERTIFICATE----- The internal certificate for gRPC connections between the gateway and the API server. DO NOT Change this! gw_private_key GUI > gw_private_key -----BEGIN RSA PRIVATE KEY----- Generated by the config wizard!!! -----END RSA PRIVATE KEY----- reverse_proxy Velociraptor supports a reverse proxy allowing you to place other applications behind the Velociraptor Oauth2/TLS server. GUI > reverse_proxy [0] GUI > reverse_proxy > [0] route GUI > reverse_proxy > [0] > route /CyberChef/ Any paths below this route will be forwarded to the given URL (and the path copied into the target) url GUI > reverse_proxy > [0] > url file:///shared/CyberChef/ The URL to forward to. This can be a file:// URL which allows you to host static files at this location. require_auth GUI > reverse_proxy > [0] > require_auth true If this is set to true, the user needs to be authenticated to Velociraptor before they are proxied. trusted_origins A list of domains that we will trust to send us the CSRF token. Use this only when serving the JS from a different domain than the API server. GUI > trusted_origins www.example.com GUI > trusted_origins initial_users When the Velociraptor server starts for the first time, the server can create the following initial user with admin level access. This is designed to automate deployment and allow users to sign in immediately to the GUI. You can remove these accounts or change their ACLs/Roles later. GUI > initial_users [0] GUI > initial_users > [0] name GUI > initial_users > [0] > name mic Username to create password_hash GUI > initial_users > [0] > password_hash aa3a779e09062dea3a46811e0c0624ba7999cf15a2d12dce7489aca339c3deff Password hashes - this is only useful for Basic Authenticator which uses passwords. They can be left empty for Oauth based authenticator. password_salt GUI > initial_users > [0] > password_salt f8707a7a9c876a4e6210d4f5bbdee4846adff7465d50efc43a305175aab8f146 initial_orgs When Velociraptor starts the first time these orgs will be created. GUI > initial_orgs [0] GUI > initial_orgs > [0] org_id GUI > initial_orgs > [0] > org_id O1234 name GUI > initial_orgs > [0] > name My Company nonce GUI > initial_orgs > [0] > nonce O1234 If this is empty we use the org id. The nonce is a shared secret in the client configuration which binds clients to this Org. See Client.nonce. authenticator How to authenticate users to the server. Velociraptor comes with a large number of authenticators. This section configures the authenticator to use. GUI > authenticator type GUI > authenticator > type basic The type of authenticator to use. Currently: basic, google, azure, oidc-cognito (prior to v0.75.6), github, saml, oidc, multi saml_certificate GUI > authenticator > saml_certificate -----BEGIN CERTIFICATE----- -----END CERTIFICATE----- Used by SAML authenticator saml_private_key GUI > authenticator > saml_private_key -----BEGIN RSA PRIVATE KEY----- -----END RSA PRIVATE KEY----- saml_idp_metadata_url GUI > authenticator > saml_idp_metadata_url http://localhost:8080/simplesaml/saml2/idp/metadata.php saml_root_url GUI > authenticator > saml_root_url https://localhost:8889 saml_user_attribute GUI > authenticator > saml_user_attribute email saml_allow_idp_initiated GUI > authenticator > saml_allow_idp_initiated false Allow IdP-initiated SAML flow. saml_user_roles This feature allows roles to be set in the SAML claims. It is a similar feature to the OIDC Role setting below but less flexible. If you need more flexibility, prefer to use the OIDC flow. When these are configured, any user that authenticated with SAML will receive these roles on all the orgs. These roles are the minimum roles the user can have - you can add more roles via the GUI NOTE: roles are additive which means you can not revoke the roles from the IDP. If you need this use the OIDC flow below with the override_acls flag. GUI > authenticator > saml_user_roles analyst GUI > authenticator > saml_user_roles investigator GUI > authenticator > saml_user_roles oidc_issuer GUI > authenticator > oidc_issuer URL to OIDC Configuration Document. The configuration should be available in the ‘oidc_issuer + /.well-known/openid-configuration’ endpoint. oidc_name GUI > authenticator > oidc_name Company Name Name of this authenticator to show in the GUI (e.g company name). Note that you can provide many OIDC authenticators as part of the multi authenticator so having a name here helps keep them recognizable. oidc_auth_url_params Additional URL parameters that should be added to the OIDC redirect URL. GUI > authenticator > oidc_auth_url_params Key GUI > authenticator > oidc_auth_url_params > Key Value avatar GUI > authenticator > avatar http://www.example.com/icon.png oauth_client_id GUI > authenticator > oauth_client_id C123445 These are required for the oauth flow - get from the OIDC provider. oauth_client_secret GUI > authenticator > oauth_client_secret X23456 oidc_debug GUI > authenticator > oidc_debug false When this is set we emit detailed logging. Turn this on when configuring the server initially if you want to debug your OIDC setup. You probably do not want this enabled in production. claims Additional OIDC claims configuration. This is an experimental setting and should not be used except for specific situations. GUI > authenticator > claims username GUI > authenticator > claims > username email The name of the claim that represents the username (by default this is ’email’). Be careful that this MUST be unique across the domain! It is vulnerability to allow something like ’name’ across a public domain because anyone can set this name in their OIDC accounts! roles GUI > authenticator > claims > roles The field that specifies the roles. If this not set (the default), we do not allow roles to be set via OIDC. You must configure your OIDC server to send specific roles in this claim (the claim can be named for example ‘roles’). If this is configured we use the role map below to assign Velociraptor roles based on the OIDC server’s roles. NOTE: The roles will be assigned to the user in all orgs. role_map A mapping between OIDC claim roles and Velociraptor roles. For example: GUI > authenticator > claims > role_map Velociraptor.Reader GUI > authenticator > claims > role_map > Velociraptor.Reader roles GUI > authenticator > claims > role_map > Velociraptor.Reader > roles reader GUI > authenticator > claims > role_map > Velociraptor.Reader > roles allow_unverified_email GUI > authenticator > claims > allow_unverified_email false Velociraptor usually requires the email_verified claim before we can trust the email claim and use it as the username. However, some IDP (e.g. Azure) do not set this. If you want to ignore this requirement, set the below to true. override_acls GUI > authenticator > claims > override_acls false When this is set, the OIDC roles override (clear) existing velociraptor roles. The default behavior is to ensure the user’s ACL contains at least the OIDC roles. This is needed if you want to be able to remove access from the IDP. tenant GUI > authenticator > tenant O... This is specifically required by the Azure authenticator only. auth_redirect_template GUI > authenticator > auth_redirect_template http://www.google.com URL to redirect to on Unauthorized API call. If blank we just cycle to the logon screen again. default_roles_for_unknown_user Certs authenticator: If a user presents a certificate but does not exist in the system, the user will automatically receive a default role. If this is not set the user will be rejected and you will have to manually add the user to a role before they are allowed. GUI > authenticator > default_roles_for_unknown_user administrator GUI > authenticator > default_roles_for_unknown_user default_session_expiry_min GUI > authenticator > default_session_expiry_min 1440 How long to keep the session alive between auth flows - default 24 hours sub_authenticators Used by the multi authenticator to provide multiple authenticators. NOTE: Sub authenticators must be oauth based (i.e. not basic auth). GUI > authenticator > sub_authenticators [0] GUI > authenticator > sub_authenticators > [0] type GUI > authenticator > sub_authenticators > [0] > type Google CA This is the internal Velociraptor CA configuration. It is needed to sign new API keys. Secure deployments can remove this part of the config and safely store it offline. CA private_key CA > private_key -----BEGIN RSA PRIVATE KEY----- -----END RSA PRIVATE KEY----- CA private key - the public certificate is in Client.ca_certificate Frontend Configuration of the frontend. The Frontend is the service that directly talks with clients. Frontend base_path Frontend > base_path / Serve the Frontend from this base path instead of “/” use_plain_http Frontend > use_plain_http false This allows the frontends to listen on plain HTTP - It is useful if you have SSL offloading (e.g. nginx). This is not configured by the wizard - you will need to manually configure it. You better know what you are doing here! require_client_certificates Frontend > require_client_certificates false Enabling this requires the clients to present a valid certificate (signed by one of the Root CAs listed in Client.Crypto.root_certs or the Velociraptor built in CA itself). NOTE: If you use configurations that place the Frontend and the GUI on the same port then you MUST use the ClientCertificate authenticator. See further discussions at Client.Crypto.client_certificate. If this setting is enabled it becomes more difficult to troubleshoot the server since a simple curl command will be rejected. To test connectivity with the server you should instead provide client cert and key files: curl -kv https://localhost:8000/server.pem –cert client.pem –key key.pem proxy Frontend > proxy http://127.0.0.1:3128 A proxy setting to use - Velociraptor needs to connect to download tools. This setting will force it to go out over this proxy. NOTE- If you don’t want to allow outbound connections, just set this to an non-existent setting (e.g. http://127.0.0.1:3128). SECURITY: This proxy setting and the proxy_config below control ALL server-initiated outbound HTTP connections, including tool materialization and VQL’s http_client() plugin. Without a proxy or with a permissive proxy, any user with admin-equivalent permissions can make the server fetch arbitrary URLs, including internal RFC 1918 addresses and cloud endpoints. Set a restrictive proxy or configure proxy_url_regexp to limit outbound destinations proxy_config These proxy settings are exactly the same as the Cllient.proxy_config settings but apply to the server. Frontend > proxy_config http Frontend > proxy_config > http <not set> https Frontend > proxy_config > https <not set> proxy_url_regexp Frontend > proxy_config > proxy_url_regexp ^https://localhost/ Frontend > proxy_config > proxy_url_regexp > ^https://localhost/ pac Frontend > proxy_config > pac <not set> ignore_environment Frontend > proxy_config > ignore_environment false do_not_compress_artifacts Frontend > do_not_compress_artifacts true Velociraptor can attempt to obfuscate artifact names when compiling them into raw VQL. If this is set to false this obfuscation is removed. hostname Frontend > hostname 192.168.1.11 The publicly accessible hostname of the frontend. bind_address Frontend > bind_address 0.0.0.0 Which interface to bind to. Usually the frontend is bound to 0.0.0.0 to allow all clients to connect from anywhere. bind_port Frontend > bind_port 8000 certificate Frontend > certificate -----BEGIN CERTIFICATE----- -----END CERTIFICATE----- These are used to secure the client/server communications - Even when using external TLS certificates! This certificate must be signed by the Velociraptor root CA in all cases (tls_certificate_filename for that). If using an external TLS configuration this layer of encryption happens in addition to the external TLS certificates. private_key Frontend > private_key -----BEGIN RSA PRIVATE KEY----- -----END RSA PRIVATE KEY----- tls_certificate_filename Frontend > tls_certificate_filename /etc/cert.pem If you want to use your own certificates for TLS as an alternative to Autocert, then you can set those here. These certificates will be used for TLS on both the frontend and GUI. NOTE: We expect these to be proper certificates - i.e. NOT self signed. If you want to use certificates issued by another CA you will also need to add that CA cert to the Client.Crypto.root_certs field. Be sure to set Client.use_self_signed_ssl=false when you set this. tls_private_key_filename Frontend > tls_private_key_filename /etc/cert.key dyn_dns If configured, Velociraptor will attempt to update the dynamic DNS server with its public IP address. Currently we only support a number of providers including noip and cloudflare. Frontend > dyn_dns type Frontend > dyn_dns > type noip The type of DynDNS provider (Can be cloudfront or noip) hostname Frontend > dyn_dns > hostname www.velo.com The hostname to update ddns_username Frontend > dyn_dns > ddns_username 1234233452 ddns_password Frontend > dyn_dns > ddns_password 2313e2324 ddns_hostname Frontend > dyn_dns > ddns_hostname <not set> The hostname to update - if empty we use Frontend.hostname update_url Frontend > dyn_dns > update_url http://dyndns.provider.com/ If empty we use Google Domains. frequency Frontend > dyn_dns > frequency 60 How often to check for IP assigned checkip_url Frontend > dyn_dns > checkip_url http://dyndns.provider.com/checkip The url we will use to check the ip. Should return a plain IP address (default is Google Domains) dns_server Frontend > dyn_dns > dns_server 8.8.8.8:53 DNS server we query for our own hostname/ip mapping (default 8.8.8.8:53) api_token Frontend > dyn_dns > api_token <not set> Used by the cloudfront provider zone_name Frontend > dyn_dns > zone_name <not set> The zone to update (dns domain). proxy_header Frontend > proxy_header X-Forwarded-For Header defined by the proxy containing the remote address. If this is not set we use the remote IP address from the TCP connection. This setting is needed if you have a reverse proxy in front of the server. default_server_monitoring_artifacts We have the Server.Monitor.Health enabled always but these are any additional artifacts that should be installed by default. Frontend > default_server_monitoring_artifacts Server.Monitor.Health Frontend > default_server_monitoring_artifacts default_client_monitoring_artifacts When creating the initial client monitoring artifact table, these artifacts will be assigned to all clients. Frontend > default_client_monitoring_artifacts Generic.Client.Stats Frontend > default_client_monitoring_artifacts run_as_user Frontend > run_as_user velociraptor The user that the frontend should run as. If set we refuse to run as a different user. This is normally set by the Ubuntu deb package as it is running as a low privilege user called “velociraptor”. This setting is important as it stops users from running velociraptor as root with sudo - doing this will break the velociraptor datastore when it creates files only readable by root. initial_server_artifacts When the server is created initially, these server artifacts will be collected. You can use this to fire custom initialization sequences. Frontend > initial_server_artifacts MySpecialArtifact Frontend > initial_server_artifacts GRPC_pool_max_size Frontend > GRPC_pool_max_size 100 Number of gRPC connections in the pool to use to connect to the API server. GRPC_pool_max_wait Frontend > GRPC_pool_max_wait 60 artifact_definitions_directory Frontend > artifact_definitions_directory /tmp/ Load artifacts from this directory at startup collection_error_regex Frontend > collection_error_regex ERROR: A regular expression that if matches any log messages from the client’s query represent a failure of the collection. Marking the collection as failed can highlight potential problems with the VQL so this regex tries to detect common issues (e.g. Symbol not found) to draw attention to failures. resources Sets resource limitations on the server. These parameters represent the set of tunable parameters you can use to optimize performance on loaded servers. Frontend > resources connections_per_second Frontend > resources > connections_per_second 300 Load shed connections faster than this to preserve stability. notifications_per_second Frontend > resources > notifications_per_second 1000 The rate at which we notify clients of new work (e.g. a new hunt is started). Slower notification rate helps to slow down the swarm effect and reduced load on the server. enrollments_per_second Frontend > resources > enrollments_per_second 100 How quickly do we enroll clients (default 100/s, -1 to disable enrollments) concurrency Frontend > resources > concurrency 20 The maximum number of concurrent client connections we can process. Concurrency limits helps to ensure the server is not overloaded serving too many clients at the same time. Concurrency refers to the actual serving time of a client (i.e. time taken to read the response and write to the datastore), not the total number of clients served by server. Default is number of cores * 2. concurrency_timeout Frontend > resources > concurrency_timeout 600 The maximum time a client will be waiting for a concurrency slot before timing out. A small value will result in many reconnections under load and may degrade performance. max_upload_size Frontend > resources > max_upload_size 10485760 Increasing this allows the frontend to receive larger POST messages lowering crypto overheads but this comes at the expense of more memory use. expected_clients Frontend > resources > expected_clients 10000 This setting controls the size of various LRU caches in the frontend (e.g. the session key cache, client info cache). This number should be larger than the number of actual clients or else the system will see high CPU load from cache misses. per_client_upload_rate Frontend > resources > per_client_upload_rate 0 Bandwidth control: Per client and global rates in bytes/sec. This is useful for low bandwidth deployments where we want to ensure Velociraptor does not saturate slow links. The bandwidth limitation caps the total bandwidth used by the server per client and globally. global_upload_rate Frontend > resources > global_upload_rate 0 client_event_max_wait Frontend > resources > client_event_max_wait 100 Wait time for collecting events from clients - smaller means less latency to respond to client events but also means more TLS handshake and network overheads due to frequent POST. minion_batch_wait_time_ms Frontend > resources > minion_batch_wait_time_ms 10 Minions batch updates to the master so as to minimize RPC as much as possible, this controls how often these batches are flushed to the master (default 10 sec). client_info_lru_ttl Frontend > resources > client_info_lru_ttl 0 Number of seconds before expiring client info cache entries. Default (0) means do not expire at all. Expiring client info from cache too frequently can result in a lot more IO. Default size of this cache is the expected_clients above. client_info_sync_time Frontend > resources > client_info_sync_time 0 How often to sync client info records (ms) between minion and master. client_info_write_time Frontend > resources > client_info_write_time 0 max_journal_buffer_size Frontend > resources > max_journal_buffer_size 1000000000 The journal files are used to queue messages between event generators and event consumers when the consumer is unable to drain these quickly enough. The setting specifies the maximum size of the file - when it is exceeded, the file will be truncated and events will be lost. Default is 1gb index_snapshot_frequency Frontend > resources > index_snapshot_frequency 10 How often to save an index snapshot to storage (default 600 sec). Index files are typically 150kb / 1000 clients. Datastore Velociraptor has a datastore abstraction and can use a number of possible data storage engines. This section configures the data store implementation. Datastore implementation Datastore > implementation FileBaseDataStore The data store implementation to use. This is usually set to FileBaseDataStore. location Datastore > location /mnt/data The directory under which we store small files. filestore_directory Datastore > filestore_directory /mnt/data Larger result sets and uploads are stored in the filestore_directory. This is usually the same as the location setting but it can be different to keep larger slower storage options away from smaller and faster data. memcache_write_mutation_max_age Datastore > memcache_write_mutation_max_age 1 How long before a write is forced from the pool for delayed writes memcache_write_max_memory Datastore > memcache_write_max_memory 100000000 Maximum amount of data cached in memory before we force it to be flushed to disk. Default 100mb minion_implementation Datastore > minion_implementation RemoteFileDataStore When using a master/minion setup it is necessary to have the Master and Minion nodes use different filesystem implementations. These more specific parameters can control datastore implementations on the master and minion separately. master_implementation Datastore > master_implementation MemcacheFileDataStore max_dir_size Datastore > max_dir_size 50000 Cap directories to this size after reporting error - this should not happen normally but may happen if the deployment has been very active or due to a bug! min_allowed_file_space_mb Datastore > min_allowed_file_space_mb 50 Set to the min required disk space. When we fall below this available disk space, we refuse to write files. This avoids the possibility of writing corrupted files. Default is 50mb. Set to -1 to disable disk space monitoring. disk_check_frequency_sec Datastore > disk_check_frequency_sec 10 How often to check the disk space (default 10 sec) memcache_expiration_sec Datastore > memcache_expiration_sec 6000 The following apply to the MemcacheFileDataStore How long to expire the memcache (default 10 min) memcache_write_mutation_buffer Datastore > memcache_write_mutation_buffer 100 How many mutations to queue up ahead of busy writers. By default 0 means writes will be blocked until they are handed off to a writer thread. Set to -1 to disable asynchronous writes. memcache_write_mutation_writers Datastore > memcache_write_mutation_writers 100 The MemcacheFileDataStore separates writers into a writing pool. These set the number of writer threads in that pool. Number of writing threads - increase for high latency filesystems (default 100). memcache_write_mutation_min_age Datastore > memcache_write_mutation_min_age 1000 How long to delay writes so they can be combined. This applies for writing result sets - we keep the writes in memory for min_age seconds in order to combine further writes. If another write occurs to the same result sets the TTL is extended and writes are delayed. However, once we reach max_age, a write is forced. The aim is to keep combining separate writes as much as possible into larger writes but at the same time prevent frequently written files from never flushing to disk. int64 memcache_write_mutation_max_age Datastore > int64 memcache_write_mutation_max_age 5000 memcache_datastore_max_size Datastore > memcache_datastore_max_size 10000 MemcacheFileDataStore will cache small files in memory to improve efficiency. This is the maximum size of the cache. Maximum size of memcache lru (default 10000) memcache_datastore_max_item_size Datastore > memcache_datastore_max_item_size 1000 Do not cache large objects in memory - falls back to FileBaseDataStore memcache_datastore_max_dir_size Datastore > memcache_datastore_max_dir_size 50000 compression Datastore > compression zlib The compression mode for collections. This setting allows compressed results to be stored on the server. For performance reasons, the client must compress the data into chunks and the server simply writes the results to storage. This means it is only supported by clients more recent than 0.75. Allowed settings: none: No compression - disable compression in client transmission. Note that for older clients (prior to 0.75), compression is not supported anyway, but this setting will disable compression on new clients as well. zlib: Zlib compression enabled on collections. This is the default setting when communicating with newer clients. max_object_size Datastore > max_object_size 4194304 The maximum size of stored objects in the datastore. The Datastore is assumed to contain smallish objects which are read and written atomically. This setting places a limit on the size of these objects to maintain efficiency and speed. If you hit this limit it means that you need to rethink your approach. See https:docs.velociraptor.app/knowledge_base/tips/grpc_errors/ The default size is 4Mb. Logging Configure logging behavior Logging output_directory Logging > output_directory /mnt/data/logs A directory to write log files in . separate_logs_per_component Logging > separate_logs_per_component true If this is set the logs will be separated into different components (e.g. Frontend, GUI, Audit etc). This makes it easier to find the source of the log messages remote_syslog_server Logging > remote_syslog_server localhost:514 If you want to forward events to a remote syslog server, fill this server addresss or hostname. If a port is omitted we use port 514. remote_syslog_protocol Logging > remote_syslog_protocol udp The protocol to use for remote syslog (default udp). remote_syslog_components The logging components to forward. If not specified we only send Audit events. Logging > remote_syslog_components VelociraptorAudit Logging > remote_syslog_components debug Specific configuration for each log level. If a log level is not configured here it is logged as normal. Logging > debug rotation_time Logging > debug > rotation_time 8000 How often to rotate the files in seconds. max_age Logging > debug > max_age 31536000 Maximum age of each file (File will be deleted after this time (1 year). disabled Logging > debug > disabled true If this is true this log source is disabled. info Logging > info rotation_time Logging > info > rotation_time 8000 max_age Logging > info > max_age 31536000 disabled Logging > info > disabled true error Logging > error rotation_time Logging > error > rotation_time 8000 max_age Logging > error > max_age 31536000 disabled Logging > error > disabled true Monitoring This controls the Monitoring server (i.e. Prometheus) If you have a monitoring service like Grafana or Data Dog then change this server to bind to 0.0.0.0 and point your scraper at it. Monitoring bind_address Monitoring > bind_address 127.0.0.1 bind_port Monitoring > bind_port 8003 metrics_url Monitoring > metrics_url http://localhost:8003/metrics If set we use this in links etc, otherwise we take a guess based on bind_address and bind_port above. autoexec Run these automatically when the binary starts. autoexec argv When starting without any command line parameters, this argv array will be used as if it was typed on the command line. This is a way to get Velociraptor to automatically execute a function as startup when used without parameters. autoexec > argv artifacts autoexec > argv collect autoexec > argv Generic.Client.Info autoexec > argv artifact_definitions Load these artifact definitions into the binary at startup. NOTE: These definitions are considered “built-in” which will ensure they can not be modified at runtime. The format of these fields is an artifact definition - so the following description also covers artifact definitions more generally. autoexec > artifact_definitions [0] autoexec > artifact_definitions > [0] name autoexec > artifact_definitions > [0] > name Generic.Client.InfoXXX The name of the artifact. Artifacts are referred to by name within the system. description autoexec > artifact_definitions > [0] > description Artifact Description A Human readable description of the artifact. This should have a single summary paragraph author autoexec > artifact_definitions > [0] > author Author The artifact author type autoexec > artifact_definitions > [0] > type CLIENT Type of the artifact: CLIENT, SERVER, CLIENT_EVENT, SERVER_EVENT reference A list of references autoexec > artifact_definitions > [0] > reference https://www.google.com autoexec > artifact_definitions > [0] > reference tools Artifacts can specify third party tools to load. Velociraptor will attempt to fetch these tools when a user wants to collect this artifact. Velociraptor will push the tool to the endpoint so the artifact may use it. autoexec > artifact_definitions > [0] > tools [0] autoexec > artifact_definitions > [0] > tools > [0] name autoexec > artifact_definitions > [0] > tools > [0] > name MyTool The name of the tool url autoexec > artifact_definitions > [0] > tools > [0] > url http://www.google.com The URL to fetch the tool from when we upload it the first time, or when we update. github_project autoexec > artifact_definitions > [0] > tools > [0] > github_project GitHubProject As an alternative to a url we allow scrapping of GitHub releases using the github API. NOTE: When this method is specified, the file will always be served locally. github_asset_regex autoexec > artifact_definitions > [0] > tools > [0] > github_asset_regex GitHubAsset serve_locally autoexec > artifact_definitions > [0] > tools > [0] > serve_locally true If set, the tool will be served locally from the filestore path - otherwise the endpoint will download the file by itself from the url above. admin_override autoexec > artifact_definitions > [0] > tools > [0] > admin_override true This is set when an admin explicitly overrides a tool. If this is set we will not update the tool definition when upgrading server versions. serve_url autoexec > artifact_definitions > [0] > tools > [0] > serve_url https://www.google.com Once the tool is added with the above fields, the following fields are used to keep state on it. The URL we serve the tool from when we serve locally. If this is empty we just let the endpoint download its own tool from the url above. serve_path autoexec > artifact_definitions > [0] > tools > [0] > serve_path Where to read the file from the filesystem Only valid for local dummy inventory. filestore_path autoexec > artifact_definitions > [0] > tools > [0] > filestore_path /public/1234 A filestore path where the file can be downloaded from - if served locally. filename autoexec > artifact_definitions > [0] > tools > [0] > filename MyTool.exe The name of the cached file on the endpoint. This file will persist and can be accessed again if this tool is needed in future. If the file is missing (or has the wrong hash), then it will be downloaded again. expected_hash autoexec > artifact_definitions > [0] > tools > [0] > expected_hash 1234 Hex encoded sha256 hash of the file. Endpoints will check this hash against their fetch file to ensure it was correctly transferred. materialize autoexec > artifact_definitions > [0] > tools > [0] > materialize true If set on a request we refresh the hash. required_permissions A list of permissions the user needs to possess before they are allowed to collect this artifact. autoexec > artifact_definitions > [0] > required_permissions EXECVE autoexec > artifact_definitions > [0] > required_permissions resources autoexec > artifact_definitions > [0] > resources timeout autoexec > artifact_definitions > [0] > resources > timeout 600 Default timeout for this artifact ops_per_second autoexec > artifact_definitions > [0] > resources > ops_per_second 100 cpu_limit autoexec > artifact_definitions > [0] > resources > cpu_limit 20 iops_limit autoexec > artifact_definitions > [0] > resources > iops_limit 20 max_rows autoexec > artifact_definitions > [0] > resources > max_rows 1000000 Default resource use for the entire collection. max_upload_bytes autoexec > artifact_definitions > [0] > resources > max_upload_bytes 1000000 precondition autoexec > artifact_definitions > [0] > precondition SELECT OS FROM info() WHERE OS =~ "windows" If the artifact specifies a precondition the client will evaluate this query before evaluating the main artifact. If the precondition returns no rows (ie. FALSE) then the artifact will not be collected. You can use the precondition to protect incompatible clients from collecting the artifact (usually the OS condition). parameters Parameters are provided to the artifact by the user. They can change the way the VQL is evaluated. autoexec > artifact_definitions > [0] > parameters [0] autoexec > artifact_definitions > [0] > parameters > [0] name autoexec > artifact_definitions > [0] > parameters > [0] > name Foo The name of the parameter. This name will appear in the scope during query execution. friendly_name autoexec > artifact_definitions > [0] > parameters > [0] > friendly_name A Foo Variable A human friendly name for the parameter (if not specified we show the name). default autoexec > artifact_definitions > [0] > parameters > [0] > default 10 A default value for the parameter. NOTE: Parameters are always strings so this field needs to be the string representation of the type - e.g. “10” rather than 10. description autoexec > artifact_definitions > [0] > parameters > [0] > description A parameter A description of this parameter to be shown in the GUI type autoexec > artifact_definitions > [0] > parameters > [0] > type int The type of this parameter. Currently one of: string, regex, yara, upload, int, int64, integer, timestamp, csv, artifactset, json, json_array, bool, choices choices For parameters of type “choices” this is a list of possible choices. autoexec > artifact_definitions > [0] > parameters > [0] > choices One autoexec > artifact_definitions > [0] > parameters > [0] > choices Two autoexec > artifact_definitions > [0] > parameters > [0] > choices export autoexec > artifact_definitions > [0] > export VQL here A snippet of VQL that can be imported by other artifacts imports A list of artifacts that will be imported by this artifact. autoexec > artifact_definitions > [0] > imports Artifact.Name autoexec > artifact_definitions > [0] > imports sources A list of queries to gather data from. autoexec > artifact_definitions > [0] > sources [0] autoexec > artifact_definitions > [0] > sources > [0] name autoexec > artifact_definitions > [0] > sources > [0] > name MySource An optional name for the query description autoexec > artifact_definitions > [0] > sources > [0] > description A description for the source query autoexec > artifact_definitions > [0] > sources > [0] > query SELECT * FROM info() queries An internal list of compiled queries. For backwards compatibility with very old artifacts. autoexec > artifact_definitions > [0] > sources > [0] > queries DO NOT USE autoexec > artifact_definitions > [0] > sources > [0] > queries precondition autoexec > artifact_definitions > [0] > sources > [0] > precondition SELECT OS FROM info() WHERE OS =~ "windows" A precondition applying to this source only. notebook An artifact source may define multiple notebook cells to be used when the artifact is collected or hunted for. autoexec > artifact_definitions > [0] > sources > [0] > notebook [0] The type of the notebook cell: e.g. suggestion adds a cell to the suggestion button. Also can be vql or markdown. autoexec > artifact_definitions > [0] > sources > [0] > notebook > [0] type autoexec > artifact_definitions > [0] > sources > [0] > notebook > [0] > type suggestion env Parameters to pre-populate in the cell. autoexec > artifact_definitions > [0] > sources > [0] > notebook > [0] > env [0] autoexec > artifact_definitions > [0] > sources > [0] > notebook > [0] > env > [0] key autoexec > artifact_definitions > [0] > sources > [0] > notebook > [0] > env > [0] > key X value autoexec > artifact_definitions > [0] > sources > [0] > notebook > [0] > env > [0] > value Y template autoexec > artifact_definitions > [0] > sources > [0] > notebook > [0] > template Text here server_type server_type linux obfuscation_nonce obfuscation_nonce zKJDb3KcWh8= This is used to obfuscate artifact names when sending to the client. NOTE: This is currently not very robust - i.e. it does not hide the artifact names very well - you should not name artifacts in a sensitive way. This value is server-only and is NOT distributed to client configuration files. Do not confuse it with Client.nonce, which is a different value that IS sent to clients for org grouping. autocert_cert_cache autocert_cert_cache /tmp/ Path to store autocert certificates. defaults Various defaults used by various things. defaults notebook_cell_timeout_min defaults > notebook_cell_timeout_min 10 Normally notebook queries timeout in 10 minutes (can not be changed from within the notebook). This is done to reduce load on the server. If you want to increase notebook timeout you can change this. notebook_default_new_cell_rows defaults > notebook_default_new_cell_rows 50 By default new cells only list 50 rows if there is no custom cell template. This is to make refreshing the cell quick. Usually users need to edit or the limit clause to see the full result table in the cell. This setting increases the default 50 rows. notebook_memory_low_water_mark defaults > notebook_memory_low_water_mark 0 When running on a shared server notebook calculations can increases memory use and affect other users. The following settings control notebook calculations to ensure they do not use too much memory. You should set the following in accordance with the VM settings of the server with a small margin of safety. When calculating a new cell we do not start calculation until the process memory is smaller than the low memory mark. notebook_memory_high_water_mark defaults > notebook_memory_high_water_mark 0 When the process memory exceeds the high water mark, we actively cancel in flight notebook cell calculations to bring memory use down. notebook_number_of_local_workers defaults > notebook_number_of_local_workers 5 Since Version 0.7.1, notebook queries are run in separate worker threads, even on single server configurations. This parameters sets the number of workers available. Set to -1 to disable local workers. The default is 5 local workers. If you want the master to not perform any notebook computations reduce this to -1 and set Minion.notebook_number_of_local_workers to 5. notebook_wait_time_for_worker_ms defaults > notebook_wait_time_for_worker_ms 10000 Wait this long for a worker to become available before giving up. The default is 10 seconds. notebook_worker_priority defaults > notebook_worker_priority 10 The default priority of notebook processors (Higher priority will receive jobs over lower priority). csv_delimiter defaults > csv_delimiter , When exporting to CSV from the GUI the usual separator is comma (,). This setting allows to change the default to any single character. hunt_expiry_hours defaults > hunt_expiry_hours 168 By default hunts expire in 7 days but you can change this using this setting. event_max_wait defaults > event_max_wait 100 Default value of max_wait and relevant jitter for new event queries the GUI creates. event_max_wait_jitter defaults > event_max_wait_jitter 30 event_change_notify_all_clients defaults > event_change_notify_all_clients false If set we actively notify all clients as soon as event table is changed. This causes a lot of load on large deployments so it is off by default. It means that you will need to wait for the client to reconnect before it receives updates to its event table (usually about 5 min). When running velociraptor gui we set this to true in order to get a responsive GUI. artifact_definitions_directories Additional directories to load artifacts from on start up. defaults > artifact_definitions_directories /etc/artifacts/ defaults > artifact_definitions_directories max_in_memory_group_by defaults > max_in_memory_group_by 30000 The number of rows to keep in memory during a group by operation. Once this is exceeded we switch to disk mode which is a lot slower but has no memory limitations. Default 30000 acl_lru_timeout_sec defaults > acl_lru_timeout_sec 60 How long to cache ACL policies (default 60 sec) unauthenticated_lru_timeout_sec defaults > unauthenticated_lru_timeout_sec 10 Ignore messages from unauthenticated clients for this long - gives them a chance to enrol first (default 10 sec). export_concurrency defaults > export_concurrency 10 Controls how exports work (creating hunt or collection exports to a zip file). On slow filesystems, increase the number of worker threads to increase parallelism. You can also increase the timeout if the filesystem is too slow to build large hunt zip files within the default 10 minute timeout. export_max_timeout_sec defaults > export_max_timeout_sec 600 hunt_dispatcher_refresh_sec defaults > hunt_dispatcher_refresh_sec 600 The server maintains an index of all hunts in order to quickly allow the GUI to filter/sort them. This setting controls how often to rebuild the hunt index (default 600 sec). You probably don’t need to change it. hunt_dispatcher_refresh_rate defaults > hunt_dispatcher_refresh_rate 10 The hunt dispatcher index rebuild is rate limited to reduce load on the server. This sets how fast it should go (in flows per second). You probably do not want to change this. notebook_versions defaults > notebook_versions 5 Total number of cell versions we keep for undo/redo support. watch_plugin_frequency defaults > watch_plugin_frequency 3 Watch plugin frequency sleep time in seconds: How often watch_syslog() will check for changes (default 3). watch_plugin_buffer_size defaults > watch_plugin_buffer_size 16384 Maximum length of the line that will be parsed (16kb) backup_period_seconds defaults > backup_period_seconds 86400 Period in seconds when to produce a backup. Velociraptor will generate a backup of important metadata about the server. By default this happens daily but you can change it here (set to -1) to disable backups. client_info_housekeeping_period defaults > client_info_housekeeping_period 60 The server’s client info manager runs housekeeping tasks periodically to determine if clients need to be notified. This setting controls how often to run the client info’s house keeping thread in seconds (default 60 sec) disable_unicode_usernames defaults > disable_unicode_usernames false Disable unicode usernames. By default Velociraptor allows usernames to consist of any Unicode character for i8n support, however this opens the possibility for Homoglyph attacks. Setting the following to true will restrict usernames to the set a-z and 0-9 reindex_period_seconds defaults > reindex_period_seconds 300 How often to refresh the search index (default 5 min). This rebuilds the search index periodically to avoid inconsistencies. indexed_client_metadata The client metadata is an arbitrary key/value store that holds user defined information per client. You can normally store anything in the client metadata but this information is not indexed, making searching on it slow (using VQL each client’s metadata blob needs to be opened, read and matched). This setting allows you to define some fields in the client metadata that will be indexed. These fields should not be too large so as to keep the index size smallish so it is recommended to use only small strings. Once fields are defined here, the extra data can be searched in the GUI search bar using a verb such as <field_name>:match. For example, define here: indexed_client_metadata: department Then a search for department:accounting will match all clients with the key department and value contains accounting in their client metadata. defaults > indexed_client_metadata department defaults > indexed_client_metadata disable_active_inflight_checks defaults > disable_active_inflight_checks false If this is set we do not actively check the status of in-flight collections. This is a new feature to 0.73 and may need to be disabled in some large deployments due to additional overheads. write_internal_events defaults > write_internal_events false Normally internal event artifacts are not written to disk but passed internally. For debugging it is useful to have a written record though. Enabling this will also write them to disk. Probably only useful for debugging. max_rows defaults > max_rows 0 Defaults for client communication limits. Decrease those if your clients are behind a proxy that only accepts very small POST messages. If not set we use client defaults. max_row_buffer_size defaults > max_row_buffer_size 0 max_batch_wait defaults > max_batch_wait 0 max_logs defaults > max_logs 100000 Maximum default value for log messages sent by the client for each flow. Once this is reached, the client stops sending log messages in the current collection. lockdown lockdown false The Velociraptor server may be placed into “lockdown” mode. While in lockdown mode certain permissions are denied - even for administrators. This additional protection mode helps to mitigate the case when a Velociraptor administrator’s account is compromised. The server can be taken out of lockdown mode by setting lockdown to false and restarting the server. debug_mode debug_mode false This will be set when Velociraptor is started with the –debug flag. Minion This configuration applies for minions. On minions this will override the settings elsewhere in the config file allowing an easy way to manage the difference between minions and master nodes. This override occurs at config load times so you can see the final configuration using velociraptor –minion –config server.config.yaml config show Minion notebook_number_of_local_workers Minion > notebook_number_of_local_workers 4 Used to override Defaults.notebook_number_of_local_workers notebook_worker_priority Minion > notebook_worker_priority 10 Used to override Defaults.notebook_worker_priority. By default minion workers have higher priority than the master node allowing minions to take over notebook calculations most of he time. security security allowed_file_accessor_prefix A list of path prefixes allowed for the ‘file’ accessor. If this is empty the file accessor will work on all directories. If you want to disable access to the server’s filesystem you can set this to a non existent directory, e.g. /nonexistent/ . The below shows the default list, which is used if nothing is set here. You should copy and modify the entire list to preserve the defaults. security > allowed_file_accessor_prefix /tmp/ security > allowed_file_accessor_prefix denied_file_accessor_prefix Deny takes precedent over allow. The below shows the default list, which is used if nothing is set here. You should copy and modify the entire list to preserve the defaults. security > denied_file_accessor_prefix /bin/ security > denied_file_accessor_prefix allowed_fs_accessor_prefix A list of prefixes allowed for the fs accessor. All other prefixes will be rejected. The below shows the default list, which is used if nothing is set here. You should copy and modify the entire list to preserve the defaults. security > allowed_fs_accessor_prefix artifact_definitions security > allowed_fs_accessor_prefix clients security > allowed_fs_accessor_prefix downloads security > allowed_fs_accessor_prefix notebooks security > allowed_fs_accessor_prefix public security > allowed_fs_accessor_prefix temp security > allowed_fs_accessor_prefix server_artifacts security > allowed_fs_accessor_prefix server_artifacts_logs security > allowed_fs_accessor_prefix denied_fs_accessor_prefix Deny takes precedent over allow. IMPORTANT: Setting this list replaces the built-in deny list (acl, backups, config, orgs, secrets, users) rather than merging with it. If you add custom prefixes here, you must also include any of the built-in prefixes you want to keep. security > denied_fs_accessor_prefix config security > denied_fs_accessor_prefix allowed_plugins If these are set we enforce VQL to only have the specified allowed VQL plugins and functions. This is a way to harden the server by removing potentially sensitive functionality to allow only approved VQL plugins to run. The below shows some examples but the default is actually an empty list which causes no plugins to be restricted. security > allowed_plugins glob security > allowed_plugins allowed_functions security > allowed_functions dict security > allowed_functions allowed_accessors security > allowed_accessors auto security > allowed_accessors denied_plugins Alternatively, it might be easier to deny specific plugins and functions and accessors. The below shows some examples but the default is actually an empty list which causes no plugins to be denied. security > denied_plugins execve security > denied_plugins denied_functions security > denied_functions rm security > denied_functions denied_accessors security > denied_accessors s3 security > denied_accessors lockdown_denied_permissions When the server is in lockdown mode the following permissions will be denied (Even for administrators). The below shows the default list, which is used if nothing is set here. You should copy and modify the entire list to preserve the defaults. security > lockdown_denied_permissions ARTIFACT_WRITER security > lockdown_denied_permissions SERVER_ARTIFACT_WRITER security > lockdown_denied_permissions EXECVE security > lockdown_denied_permissions SERVER_ADMIN security > lockdown_denied_permissions FILESYSTEM_WRITE security > lockdown_denied_permissions FILESYSTEM_READ security > lockdown_denied_permissions MACHINE_STATE security > lockdown_denied_permissions certificate_validity_days security > certificate_validity_days 365 Default expiry of certificate issuance (default 365 days). This will apply for e.g. rotating certificates or issuing an api cert. disable_inventory_service_external_access security > disable_inventory_service_external_access false Normally the inventory service attempts to download tools in its own but if this is set, we prevent any external access. secrets_dek security > secrets_dek The Data Encryptions Key to use for protecting the secrets in storage. This can take a number of forms: If it starts with env://<VAR> the secret will be taken from an Environment variable. If empty the secret is taken from obfuscation_nonce (which by default is the hash of the private key). In future further methods may be implemented (e.g. EKMS). See the following for more information http://docs.velociraptor.app/docs/deployment/security/#protecting-stored-secrets vql_must_use_secrets security > vql_must_use_secrets false This controls VQL plugins that may accept secrets as well full parameters. If this flag is set, those plugins will refuse to accept direct parameters, instead only accepting a secret name. This allows the admin to control exactly how these plugins work without disabling them completely. shadowed_env_vars Prevent VQL from having access to these environment variables. Environment Vars sometimes may contain secrets and confidential information. security > shadowed_env_vars VELOCIRAPTOR_CONFIG security > shadowed_env_vars